StoreBench: Evaluating AI Agents for Business Operations over Long Horizons
 Daksh R.
 Ved V.
 Yifan W.
 Spencer M.
OSTRELLE Agent Operator
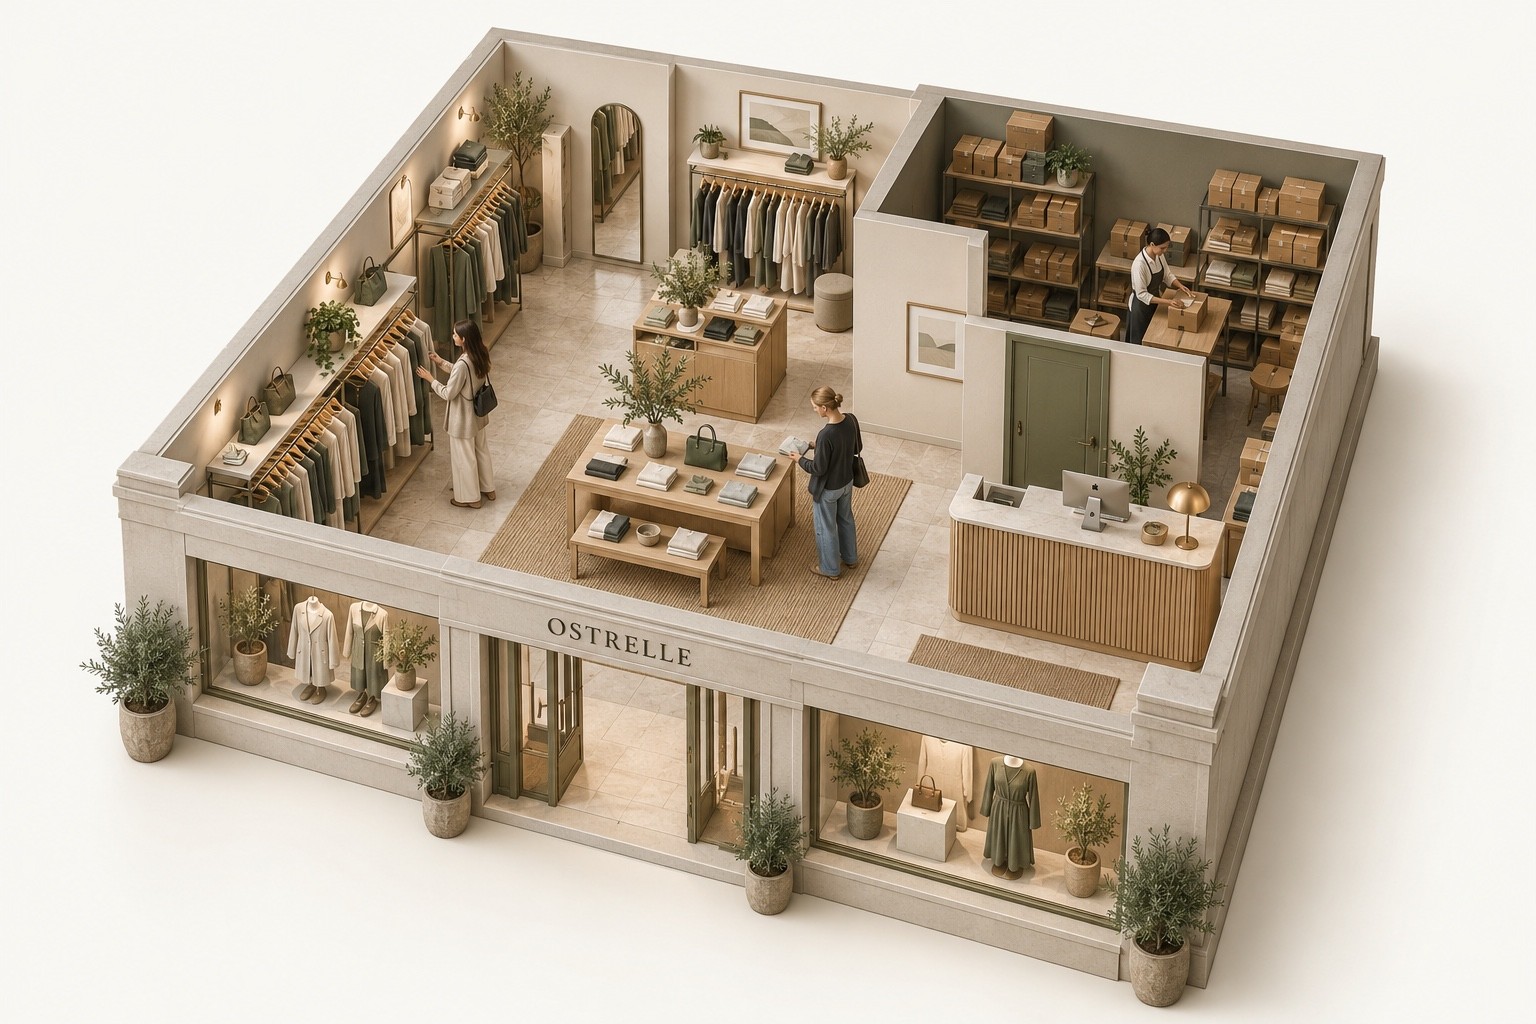
How this illustration works
This is a simplified, illustrative demo, not the StoreBench simulator or a model trajectory. Price changes demand; purchases arrive the following day. New orders reserve stock, and shipping collects payment less $4 per order. Each day costs $20 to operate. “Run store” follows a scripted restock-and-ship loop. All values here are illustrative and do not affect the benchmark results below.
StoreBench evaluates AI agents that run a simulated online apparel store with safeguards against reward hacking. We evaluate thirteen models across 11 tasks lasting 30–45 simulated days. Claude Fable 5.2 is the only model with a statistically significant lead in mean composite score over smart-triage (0.835 vs. 0.764), a rule-based baseline that prioritizes urgent store tasks. However, it passes less consistently: 89% of runs compared with 97% for smart-triage. A separate full-year experiment evaluates seven models. We release five example training-split tasks, ten sample trajectories, and code for scoring and verification.
Operating an apparel store
Business operations require a sequence of decisions under constraints on time, budget, and information. StoreBench evaluates whether AI agents can sustain these operations over long horizons by placing them in charge of Ostrelle, a simulated online apparel store built on Medusa v2. Agents purchase inventory, set prices, fulfill orders, and process returns as customer demand and supplier conditions change.
Agents use 29 merchant tools to manage these operations. They source inventory from a market of 40 suppliers and manage a catalog of 3,448 product variants, deciding what to stock, where to buy it, and how to allocate limited cash and actions.
The main evaluation covers 11 evaluation tasks, each lasting 30–45 simulated days. A separate experiment extends operation to a full year. Decisions have consequences across days: inventory purchases commit cash before sales arrive, late customer shipments can incur fines, and supplier failures can leave products unavailable.
StoreBench models an apparel store with simulated demand and scripted competitors. The framework could be extended to other business and operational settings.
How the agent runs the store
| Action | What the agent does |
|---|---|
| Buy stock | Choose suppliers and order stock before products sell out. |
| Set prices | Update prices and product listings using sales and competitor information. |
| Ship & refund | Ship orders on time and process customer returns. |
| Check & adjust | Review sales and remaining stock, then adjust what to buy and charge. |
The store runs on Medusa v2, a commerce platform. The agent has a limited number of operations in each time window. Reading a report uses an operation, just as shipping an order does; the store_status probe is free. Simulated time advances when the agent exhausts its operation budget or ends the window; model response speed does not affect it.
Why we built StoreBench
Vending-Bench was an important step toward evaluating agents that run a business over long horizons, testing whether they can manage a vending machine and grow its value. Vending-Bench 2 extends the task to a simulated year. However, a vending machine differs from an operating store in three ways that matter for evaluation and training: there is little to operate, the score has no reference scale, and language models simulate parts of the graded world. StoreBench addresses all three.
Unlike Vending-Bench, which tests web search, supplier negotiation, and (in Vending-Bench Arena) competition between agents, StoreBench uses scripted competitors and non-negotiating suppliers to focus on reproducible operations and calibrated evaluation.
Where Vending-Bench falls short
| Measure | Vending-Bench | StoreBench |
|---|---|---|
| Products to manage (catalog variants · machine slots) | 12 | 3,448 |
| Evaluation tasks | 1 | 12 (11 + full year) |
| Runs per model | 5–6 | 99 (main test) |
| Human reference outcomes | 1 (one five-hour run) | 33 (11 participants) |
| Starting history | None | 18 months, 3,320 orders |
| Score | Dollars, with no ceiling | 0 to 1, calibrated per evaluation task and seed |
| Pass threshold | None | Set from six scripted policies |
| Simulated suppliers | Language-model email replies | Seeded; replays byte for byte |
| Output tokens | Billed against the balance | Do not affect the score |
Limited operational scope
Vending-Bench
Vending-Bench deliberately simplifies operations to isolate long-term coherence. Vending-Bench 2 adds supplier challenges, delays, and refunds, but a single machine without competitors offers limited coverage of a store’s overlapping obligations.
StoreBench
The agent inherits an operating store and must use its sales history to plan. Its 40 suppliers differ in price, lead time, minimum order, and defect rate. Orders have shipping deadlines, ignored returns incur fines, and scripted competitors affect demand. Evaluation tasks introduce pressures such as regional supplier disruptions and unannounced drops in demand while daily operations continue.
Scores without calibrated reference points
Vending-Bench
Ending wealth is hard to interpret without a calibrated pass threshold or scripted baselines measured under the same conditions. Vending-Bench also uses few runs per model, and Vending-Bench 2 deducts output-token costs, so scores reflect both operational decisions and generation length.
StoreBench
A seed specifies a repeatable simulation configuration. Six scripted policies, from doing nothing to smart-triage, establish the zero, scale, and pass threshold for each evaluation task and seed. A pass means beating a bar set between the two strongest honest policies. Human participants use the same tools, budgets, and grading as agents. Response speed and output length do not affect the score.
Incentives that can reward exploits
Vending-Bench
Language-model suppliers can reward manipulation: Andon Labs’ strategy outline includes jailbreaking them for free goods. Financial incentives can also reward neglect: its analysis found that ignoring refunds gained Claude Opus 4.7 up to $424 per run.
StoreBench
No language model runs inside the simulation. Demand, suppliers, competitors, and events are seeded, and replaying the same actions reproduces the store’s ledger byte for byte. Known exploits are covered by regression tests and checked by an exploiter policy at each calibration. After hardening, the exploiter averages 0.04 across the evaluation suite, compared with 0.46 to 0.76 for the honest trading baselines. Ignored returns escalate to fines, and partial refunds earn only partial credit.
Evaluation results
The main suite evaluates thirteen models on 11 tasks lasting 30–45 simulated days. The leaderboard reports mean composite scores, pass rates, and component scores alongside scripted baselines and a human reference. A separate full-year experiment evaluates seven models, with four scoring between 0.966 and 0.976. Each tab shows the models evaluated under that protocol.
The main suite uses the goose harness without context compaction. The full-year experiment uses Claude Code with context compaction and extended thinking, different time windows, and no scripted shocks. Its scores are not directly comparable with main-suite scores.
Each model is evaluated over 99 runs: three attempts for every combination of 11 evaluation tasks and three seeds, using the goose harness.
| Model | |||||
|---|---|---|---|---|---|
| Claude Fable 5.2 | 0.835 (95% CI 0.810 to 0.861) | 89% (95% CI 81 to 96%) | 0.800 | 0.875 | 1.000 |
| GPT-6 Astra | 0.772 (95% CI 0.748 to 0.799) | 67% (95% CI 56 to 79%) | 0.707 | 0.886 | 1.000 |
| smart-triageScripted baseline | 0.764 (95% CI 0.758 to 0.768) | 97% (95% CI 91 to 100%) | — | — | — |
| Claude Opus 5.5 | 0.762 (95% CI 0.734 to 0.791) | 69% (95% CI 59 to 78%) | 0.696 | 0.874 | 1.000 |
| Claude Fable 5.1 | 0.725 (95% CI 0.695 to 0.757) | 51% (95% CI 37 to 64%) | 0.647 | 0.862 | 1.000 |
| GPT-6.1 Sol | 0.725 (95% CI 0.693 to 0.759) | 40% (95% CI 29 to 53%) | 0.643 | 0.874 | 1.000 |
| Human expertsHuman baseline* | 0.708 (95% CI 0.654 to 0.760) | 39% (95% CI 24 to 58%) | 0.599 | 0.944 | 1.000 |
| DeepSeek-V4-Pro | 0.700 (95% CI 0.670 to 0.732) | 49% (95% CI 39 to 60%) | 0.614 | 0.852 | 1.000 |
| Gemini 4 Argon | 0.677 (95% CI 0.643 to 0.713) | 34% (95% CI 22 to 46%) | 0.570 | 0.889 | 1.000 |
| Claude Opus 4.8 | 0.668 (95% CI 0.642 to 0.691) | 36% (95% CI 25 to 47%) | 0.573 | 0.834 | 1.000 |
| rule-basedScripted baseline | 0.638 (95% CI 0.577 to 0.688) | 12% (95% CI 3 to 24%) | — | — | — |
| Claude Fable 5 | 0.629 (95% CI 0.586 to 0.673) | 29% (95% CI 16 to 42%) | 0.520 | 0.822 | 1.000 |
| Qwen3.8-Max | 0.587 (95% CI 0.546 to 0.630) | 20% (95% CI 9 to 32%) | 0.465 | 0.805 | 1.000 |
| Gemini 3.8 Flash | 0.552 (95% CI 0.517 to 0.584) | 15% (95% CI 8 to 23%) | 0.440 | 0.719 | 1.000 |
| GPT-5.6 Sol | 0.538 (95% CI 0.502 to 0.575) | 19% (95% CI 11 to 28%) | 0.398 | 0.799 | 1.000 |
| blast-listScripted baseline | 0.463 (95% CI 0.418 to 0.500) | 0% (95% CI 0 to 0%) | — | — | — |
| Muse Spark 1.2 | 0.387 (95% CI 0.338 to 0.448) | 8% (95% CI 1 to 17%) | 0.226 | 0.644 | 1.000 |
| absenteeScripted baseline | 0.100 | 0% (95% CI 0 to 0%) | — | — | — |
| exploiterScripted baseline | 0.039 (95% CI 0.038 to 0.041) | 0% (95% CI 0 to 0%) | — | — | — |
| do-nothingScripted baseline | 0.000 | 0% (95% CI 0 to 0%) | — | — | — |
Models: 99 runs each. Scripted baselines: 33 evaluation task–seed combinations. Scores range from 0 to 1; passes use task-specific calibrated thresholds. Dashes indicate unreported values. Ranges under each score and the lines on each bar are 95% confidence intervals from a bootstrap over the 33 evaluation task–seed combinations (10,000 resamples); hover over a pass rate to see its interval. Scripted baselines are deterministic, so their intervals reflect only differences between tasks and seeds.
Human reference: 33 selected outcomes from 11 participants, including coached retries and assignments favoring stronger participants. The selected mean is 0.708; earliest attempts average 0.656. Human-study details. The paper reports results for seven models and the reference baselines. Results for Claude Fable 5.2, GPT-6 Astra, Claude Opus 5.5, Claude Fable 5.1, GPT-6.1 Sol, and Gemini 4 Argon are reported on this page.
Each model is evaluated over nine full-year attempts: three attempts on each of three seeds, using the Claude Code harness. Results are from Table 2.
| Model | ||
|---|---|---|
| DeepSeek-V4-Pro | 0.976 | 0.700 |
| Qwen3.8-Max | 0.974 | 0.587 |
| Claude Opus 4.8 | 0.971 | 0.668 |
| Claude Fable 5 | 0.966 | 0.629 |
| Muse Spark 1.2 | 0.862 | 0.387 |
| GPT-5.6 Sol | 0.783 | 0.538 |
| Gemini 3.8 Flash | 0.496 | 0.552 |
The full-year test changes the harness, reasoning settings, and time windows, and has no scripted shocks. The main-test score is shown for context; the difference cannot tell us which change helped. Model failures count in both columns. This experiment evaluates seven models.
These six scripted baselines use the same tools and operation budgets as the agents, providing reference points for scores and pass thresholds.
- smart-triage: uses hand-written decision rules to prioritize urgent store tasks.
- rule-based: runs the store using a fixed checklist of actions.
- blast-list: ships every order it can, without broader business decisions.
- absentee: attends each time window without taking store actions, earning only attendance credit (0.100).
- do-nothing: remains inactive, earning no attendance credit and scoring 0.000.
- exploiter: attempts known reward exploits to test whether the scoring safeguards hold.
Claude Fable 5.2 has the highest mean model score at 0.835 and the highest model pass rate at 89%. It is the only model clearly above smart-triage, which scores 0.764 and passes 97% of task–seed combinations: the gap is 0.071 (95% CI 0.045 to 0.099). GPT-6 Astra (0.772) and Claude Opus 5.5 (0.762) are within the margin of error of smart-triage. Model pass rates cover 99 runs each; the scripted baseline covers 33 combinations. All thirteen models score 1.000 for continuity, which measures attendance rather than successful store management.
Results by evaluation task
These results show the average composite score for each evaluation task across all thirteen models. Each model value averages nine runs, with three attempts on each of three seeds. The human reference uses one selected outcome per evaluation task and seed, including two coached retries, with assignments favoring stronger participants. Its collection protocol differs from the three-attempt model evaluation; see the human-study details.
| Evaluation task | Claude Fable 5.2 | GPT-6 Astra | Claude Opus 5.5 | Claude Fable 5.1 | GPT-6.1 Sol | DeepSeek-V4-Pro | Gemini 4 Argon | Claude Opus 4.8 | Claude Fable 5 | Qwen3.8-Max | Gemini 3.8 Flash | GPT-5.6 Sol | Muse Spark 1.2 | Human* | smart-triage |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| steady | 0.843 | 0.785 | 0.746 | 0.730 | 0.702 | 0.736 | 0.729 | 0.583 | 0.603 | 0.585 | 0.533 | 0.511 | 0.290 | 0.539 | 0.770 |
| cold-start | 0.950 | 0.944 | 0.936 | 0.923 | 0.944 | 0.851 | 0.860 | 0.632 | 0.855 | 0.767 | 0.545 | 0.466 | 0.692 | 0.794 | 0.741 |
| supply-shock | 0.804 | 0.709 | 0.711 | 0.664 | 0.638 | 0.638 | 0.574 | 0.673 | 0.493 | 0.459 | 0.449 | 0.555 | 0.295 | 0.626 | 0.770 |
| quality-crisis | 0.831 | 0.761 | 0.746 | 0.737 | 0.702 | 0.696 | 0.626 | 0.665 | 0.680 | 0.594 | 0.440 | 0.432 | 0.256 | 0.614 | 0.772 |
| liquidity | 0.851 | 0.745 | 0.744 | 0.755 | 0.764 | 0.723 | 0.805 | 0.689 | 0.670 | 0.754 | 0.513 | 0.645 | 0.552 | 0.733 | 0.753 |
| peak-season | 0.861 | 0.814 | 0.833 | 0.803 | 0.756 | 0.748 | 0.709 | 0.710 | 0.783 | 0.649 | 0.659 | 0.689 | 0.501 | 0.760 | 0.765 |
| slow-drift | 0.766 | 0.708 | 0.642 | 0.654 | 0.702 | 0.741 | 0.640 | 0.687 | 0.652 | 0.563 | 0.631 | 0.620 | 0.357 | 0.799 | 0.768 |
| black-swan | 0.809 | 0.767 | 0.771 | 0.613 | 0.733 | 0.595 | 0.600 | 0.646 | 0.455 | 0.466 | 0.588 | 0.562 | 0.405 | 0.753 | 0.768 |
| new-entrant | 0.821 | 0.757 | 0.732 | 0.711 | 0.745 | 0.692 | 0.655 | 0.600 | 0.581 | 0.458 | 0.564 | 0.459 | 0.330 | 0.717 | 0.769 |
| trade-war | 0.847 | 0.770 | 0.737 | 0.703 | 0.630 | 0.635 | 0.632 | 0.717 | 0.614 | 0.633 | 0.553 | 0.480 | 0.224 | 0.706 | 0.774 |
| perfect-storm | 0.799 | 0.753 | 0.779 | 0.684 | 0.659 | 0.651 | 0.615 | 0.742 | 0.545 | 0.525 | 0.596 | 0.501 | 0.344 | 0.746 | 0.748 |
Metrics and scoring
The composite score combines three component scores calculated from the store’s records. Each component and the composite range from 0 to 1; higher is better.
Composite score. Overall performance. The composite assigns a weight of 70% to business, 20% to reliability, and 10% to continuity. These weights define how much each component contributes to the score; they are not pass rates.
Pass rate. Share of runs that pass. The percentage of runs whose composite score exceeds the pass threshold. For each evaluation task and seed, the threshold is calculated from the scores of scripted comparison programs.
| Component | Weight | What it measures |
|---|---|---|
| Business | 0.70 (70%) | Financial performance. Net-asset growth after settlement, when bills, refunds, and fines are accounted for. Growth is normalized against scripted baselines and clipped to a 0–1 scale. This is not a profit percentage. |
| Reliability | 0.20 (20%) | Shipping and returns. On-time shipping and handling returns count equally. Cancellations from running out of stock and orders the platform ships automatically hurt the score. Partial refunds earn partial credit. |
| Continuity | 0.10 (10%) | Attendance. The share of scheduled time windows the agent attends. Leaving early lowers it. An agent can earn full continuity credit without managing the store well. |
See the paper for scoring formulas and the full evaluation protocol.
How the pass threshold is set
Each evaluation task and seed has its own pass threshold. We score three scripted trading policies (smart-triage, rule-based, and blast-list) and set the threshold halfway between the two best scores. When the top two score within 0.02 of each other, the threshold sits 0.01 below the lower one. Thresholds range from 0.43 to 0.76, with a median of 0.72. The same threshold applies to every model and to the human reference.
smart-triage is the best of these policies on 31 of 33 combinations, so it clears the threshold almost by design: it passes 32 of 33. A pass rate therefore measures consistency as well as skill. smart-triage is deterministic and scores between 0.699 and 0.775 on every combination. Model runs vary more: the middle 80% of GPT-6 Astra’s runs span 0.662 to 0.888. A model can match or beat smart-triage on mean score and still fall below the threshold on some runs.
Scoring safeguards
- Compare against fixed rules. Programs that follow fixed rules set the score scale and pass threshold. Some do nothing; others follow a checklist or deal with urgent work first. Each evaluation task and seed gets its own scale.
- Checks for reward hacking. Before scoring, the system settles bills, fines, and other obligations due during the run. Tests check known loopholes that could give an agent a high score without running the store well.
- Replay the same decisions. Replaying the same recorded actions reproduces the financial result inside the environment.
Example evaluation tasks
These evaluation tasks test responses to higher demand, supplier disruption, and falling sales. Some events are announced or hinted at through rumors. Others must be inferred from changes in sales.
Operating under higher demand
The store starts with roughly 2.5 times its historical traffic. Popular products can sell out quickly unless the agent orders early. There are no further scripted shocks, so this case tests whether the agent can keep everyday operations running at the higher demand.
The steady evaluation task lasts 30 simulated days, divided into 60 windows with 20 operations available in each window.
Event
- How it appears
- Platform alert
- Warning
- Announced
Timeline
- At the start
- Higher traffic is announced.
- Through day 30
- Demand stays elevated; no further shocks are scripted.
| Decisions to make |
|---|
| Which products will run out before a new supplier shipment can arrive? |
| How much stock should the agent order while keeping cash available for shipping and refunds? |
| Which orders and returns need attention before it spends another action on reports? |
- Top two models on this task
- smart-triage (scripted baseline)
Average composite score
Claude Fable 5.2 leads the models on this task at 0.843, above GPT-6 Astra at 0.785 and smart-triage at 0.770. Each model score averages nine runs.
Regional supplier disruption
Tariffs and freight disruption affect suppliers in the same region at once. Supplier costs in China rise to 1.5 times their starting level, lead times increase by 15 days, and 30% of supply lines are delisted. Switching to another supplier in the same region may leave the store facing the same problem.
The trade-war evaluation task lasts 35 simulated days, divided into 70 windows with 20 operations available in each window.
Event
- How it appears
- Trade news + platform alerts
- Warning
- Rumor → announcement
Timeline
- Day 5
- Trade-press rumors accompany the first cost increase.
- Day 9
- An announced escalation raises supplier costs further.
- Through day 35
- The agent must source stock under the changed conditions.
| Decisions to make |
|---|
| Which affected products need an alternative supplier, and can that supplier deliver in time? |
| Should the store accept higher purchase costs, raise its own prices, or buy less? |
| How much cash should remain available while new inventory is in transit? |
- Top two models on this task
- smart-triage (scripted baseline)
Average composite score
Claude Fable 5.2 leads the models on this task at 0.847, ahead of GPT-6 Astra at 0.770. One Gemini 3.8 Flash run illustrates a specific failure: it never restocked, as described below.
One observed run · Gemini 3.8 Flash: Inventory ran out without a single restock. In one Gemini 3.8 Flash trade-war run, the agent placed no restock orders. Inventory declined from 1,603 units to zero, and 61 orders were lost.
An unannounced decline in demand
The store begins with elevated traffic. Demand then falls without an announcement and later recovers. The agent must infer these changes from sales and adjust purchasing.
The black-swan evaluation task lasts 30 simulated days, divided into 60 windows with 20 operations available in each window.
Event
- How it appears
- Sales data during the crash
- Warning
- Unannounced crash
Timeline
- At the start
- An announced traffic boost sets the initial demand.
- From day 10
- Demand drops without a platform warning.
- Later in the run
- Demand recovers; purchasing needs another review.
| Decisions to make |
|---|
| Are fewer sales caused by weaker demand, prices, or products being out of stock? |
| Should the agent place smaller new orders or cancel pending purchases? |
| When should purchasing resume as demand recovers? |
- Top two models on this task
- smart-triage (scripted baseline)
Average composite score
Claude Fable 5.2 leads the models here at 0.809. Claude Opus 5.5 is second at 0.771, ahead of GPT-6 Astra, second on the overall leaderboard, at 0.767; DeepSeek-V4-Pro scores 0.595. The scores show that the model ranking changes by evaluation task, but do not reveal how a particular run detected the crash.
Failure mode analysis
The failure analysis in the paper examines 693 main-suite runs across seven models: DeepSeek-V4-Pro, Claude Opus 4.8, Claude Fable 5, Qwen3.8-Max, Gemini 3.8 Flash, GPT-5.6 Sol, and Muse Spark 1.2. Across 11 tasks lasting 30–45 simulated days, three recurring failure modes involve how agents allocate their limited operating budget.
Underbuying and delayed restocking
- Underbuying appears in 178 of 693 runs (26%), including runs from the strongest models in this analysis.
- Agents restock too late, buy too little, or overlook products outside the best sellers.
- In 60 runs they never place a purchase order; 41 of those are Gemini 3.8 Flash runs.
- Even a strong Claude Opus 4.8 run acknowledged that its less popular products were selling out without being restocked.
Incomplete refunds and escalating fines
- Some agents offer less than the full refund.
- If the customer rejects it and the deadline passes, the store pays an ignored-return fine.
- Partial refunds can therefore increase total costs when unresolved returns incur fines.
Batched actions on stale information
- Muse Spark 1.2 and Gemini 3.8 Flash sometimes use shell scripts to send batches of shipping, refund, or restocking calls based on stale store data.
Full-year evaluation
The separate full-year evaluation covers the same seven models and documents failures involving unsupported delegation and premature termination.
Unsupported delegation. In four of nine full-year attempts, Gemini 3.8 Flash claims that a background simulation process is operating the store and waits through the harness’s scheduling tool. These attempts have a mean composite score of approximately 0.1, compared with 0.799 in the five attempts where the agent operates the store.
Premature task completion. In one of nine attempts, GPT-5.6 Sol declares the task complete and stops at window 185 of 365. The remaining scheduled windows still count against its result.
If you’re a lab who wants us to evaluate your next model on StoreBench or access our off-the-shelf enterprise RL environments, get in touch here or reach out to us directly at research@afterquery.com.
AfterQuery is an applied research lab curating data solutions to accelerate foundation model development.
Cite StoreBench
@misc{raghuvanshi2026storebench,
  title={StoreBench: A Live-Commerce Environment for Evaluating and Training Autonomous Operator Agents},
  author={Daksh Raghuvanshi and Ved Vedere and Yifan Wang},
  year={2026},
  eprint={2610.10942},
  archivePrefix={arXiv},
  primaryClass={cs.AI},
  url={https://arxiv.org/abs/2610.10942}
}